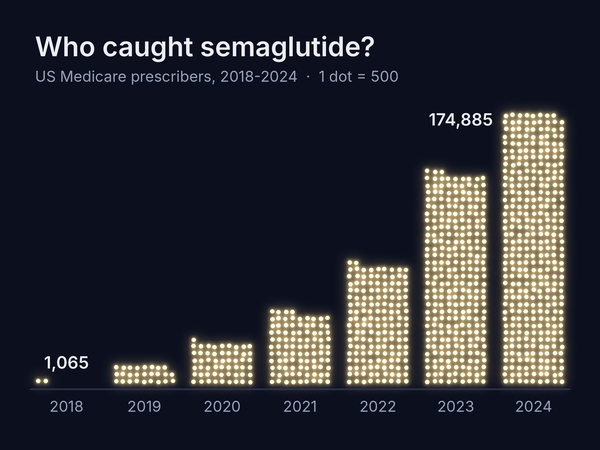
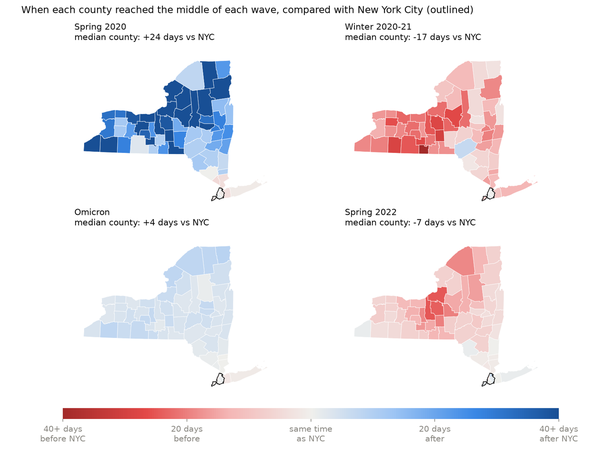
I build the data systems that healthcare decisions run on. I started my career as an epidemiologist at the New York City Department of Health, and over the last 7 years I've moved from investigating population health trends to engineering the pipelines behind them. Today I build production PySpark and Databricks pipelines that process Medicare and Medicaid claims at national scale.
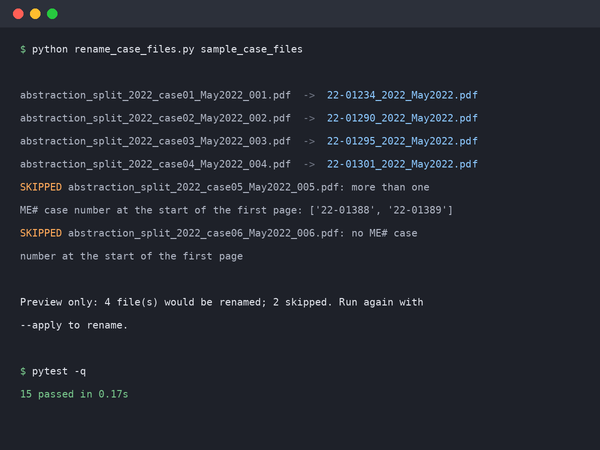
What I like most about my work is weaving different tools and languages into data systems that are scalable, tested, and easy for other people to run. I'm an investigator by nature, and my epidemiology background means I understand what the data is for, not just how it moves. I also have a knack for making technical and statistical ideas clear to any audience.
Outside work, you'll find me chilling with Euclid, hiking, reading, doing yoga and pilates, or gaming.